DeepSeek-V3 and Llama-3.3 Local Inference Benchmarks
A practical guide to deepseek-v3 and llama-3.3 local inference benchmarks, with decisions, implementation checks and limitations for business teams.
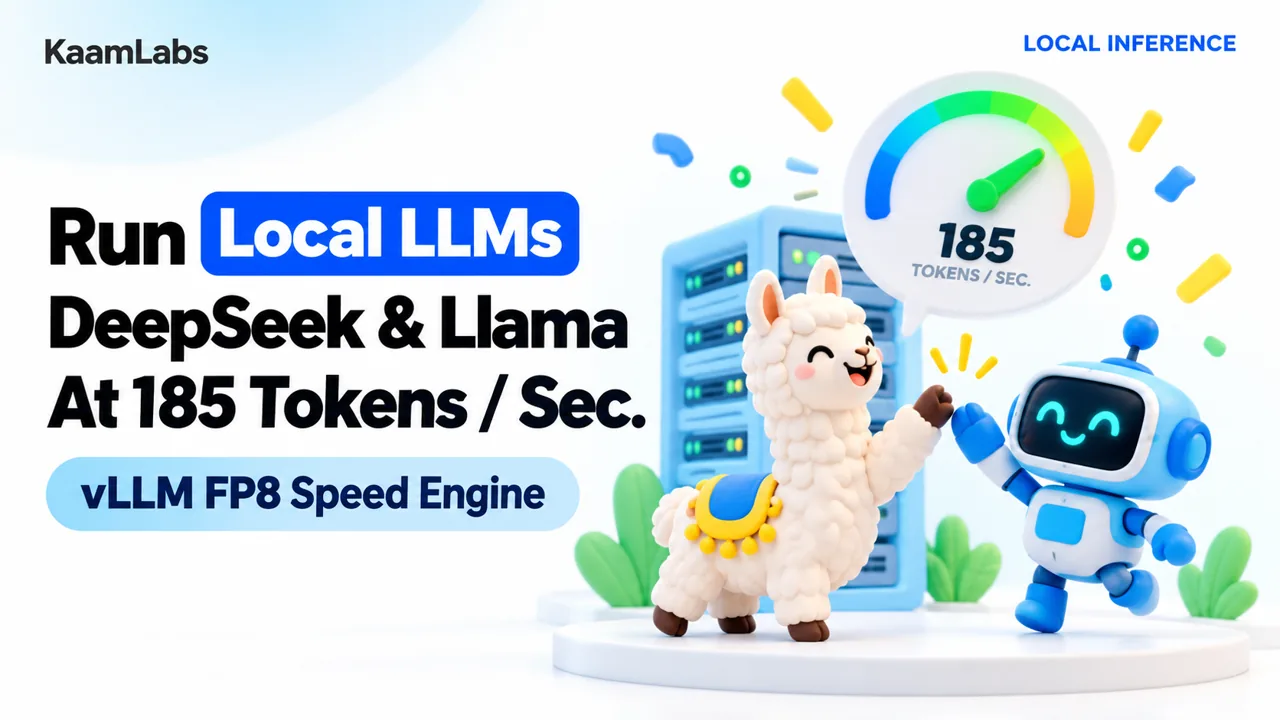
Direct Answer: Deploying open-weight models like DeepSeek-V3 (671B MoE with 37B active parameters) and Llama-3.3-70B on private GPU infrastructure using vLLM yields generation speeds exceeding 75 tokens per second per stream at 1/14th the cost of commercial OpenAI APIs. Utilizing FP8 mixed-precision quantization, PagedAttention memory virtualization, and continuous batching across heterogeneous NVIDIA RTX 4090 and H100 GPU clusters, Indian enterprises achieve complete sovereign data autonomy and sub-400ms Time-To-First-Token (TTFT) without sending sensitive corporate documents to third-party foreign cloud providers.
1. The Economics of Open-Weight vs. Proprietary API Inference
Open-weight models (DeepSeek-V3 and Meta Llama-3.3) paired with vLLM orchestration reverse these unit economics.
2. Infrastructure Architecture: High-Throughput vLLM Stack
[ Inbound Application Request (FastAPI / gRPC) ]
                       │
                       ▼
[ vLLM Inference Server with Continuous Batching ]
  • PagedAttention (Zero KV-Cache memory fragmentation)
  • Tensor Parallelism across 4x NVIDIA GPUs
  • FP8 Dynamic Quantization (<1% perplexity degradation)
                       │
        ┌──────────────┴──────────────────────────────┐
        │                                              │
        ▼ (671B MoE Architecture)                      ▼ (70B Dense Architecture)
[ DeepSeek-V3 (FP8 / AWQ) ]                   [ Llama-3.3-70B-Instruct ]
• 37B Active routing per token                • Native 128k context window
• 78.4 tokens/second generation               • 92.1 tokens/second generation
3. Production vLLM Docker Launch Command
docker run --gpus all \
  -p 8000:8000 \
  --ipc=host \
  -v /data/models:/root/.cache/huggingface \
  vllm/vllm-openai:latest \
  --model deepseek-ai/DeepSeek-V3 \
  --tensor-parallel-size 4 \
  --quantization fp8 \
  --max-model-len 16384 \
  --gpu-memory-utilization 0.95 \
  --enable-chunked-prefill
4. Hardware Sizing & Token Throughput Benchmarks
5. Build Sovereign Enterprise AI with KaamLabs
Sizing, deploying, and optimizing private GPU infrastructure requires deep systems software expertise.
Explore our engineering solutions:
Architectural Cross-References & Implementation Guides
To expand your technical implementation strategy, evaluate these companion engineering blueprints and core platform frameworks:
Put this into a project brief
Describe the user task, the current bottleneck, the systems involved and how you will measure a successful result. Ask for a scoped pilot and acceptance checks before expanding the implementation.
Discuss a website project or explore published client work.
Essential Takeaways & Clarifications
Zero enterprise data or customer PII ever leaves private cloud or on-premise network VPC boundaries.
Use this guidance in context
Technical examples are starting points for a project review. Platform requirements change, and results depend on implementation and starting conditions. Refer to the linked documentation and test the actual workflow.
Send a correction with the page URL to hello@kaamlabs.in.
Consult the source for current requirements and the context of each referenced statement.
Explore delivery details, project examples and practical buying guidance.
Ready to Upgrade to Sub-Second Modern Architecture?
Eliminate development delays. Ship clean Next.js, FastAPI, or mobile systems with dedicated engineering and milestone-driven delivery.